Predictable Shared Last-level Caches
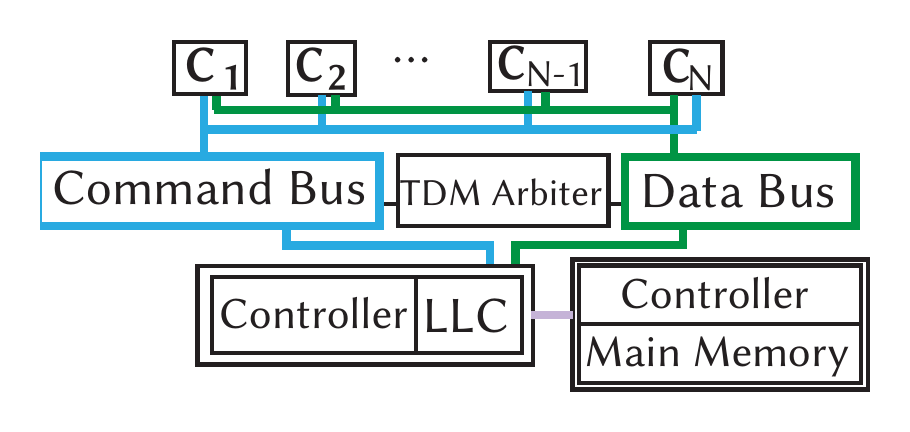
A shared last-level cache (LLC) gives multicores extra caching capacity, but cores contend for it, and in safety-critical systems every memory access needs a worst-case latency (WCL) bound. The usual fix, giving each core its own partition, uses the cache poorly, and the problem gets worse as core counts grow.
This project designs shared LLCs that keep the WCL low while still delivering the performance benefits of sharing.
- Sharing partitions. An approach to share LLC partitions among multiple cores while still providing low WCL bounds.
- ZeroCost-LLC. A shared inclusive LLC that adds no cost to the WCL compared with having no LLC at all. It eliminates cache-line invalidations across the hierarchy and places no constraints on how cores use the LLC. The journal version adds ZCLLC-OPT, with optimized bus arbitration and overlapping memory requests, lowering the WCL further and improving average performance.
- Exclusive hierarchies. PECC is a predictable exclusive coherence mechanism. An exclusive hierarchy eliminates back-invalidations, one of the largest contributors to the WCL of inclusive hierarchies, so PECC lowers the bound and improves average performance.
- Isolation with shared data. ParRP partitions the cache’s replacement policy rather than its entries, which isolates each core’s cache space even when cores share data.
See also Predictable Cache Coherence.